GPT-6 improves reuse of context for cheaper, faster long tasks
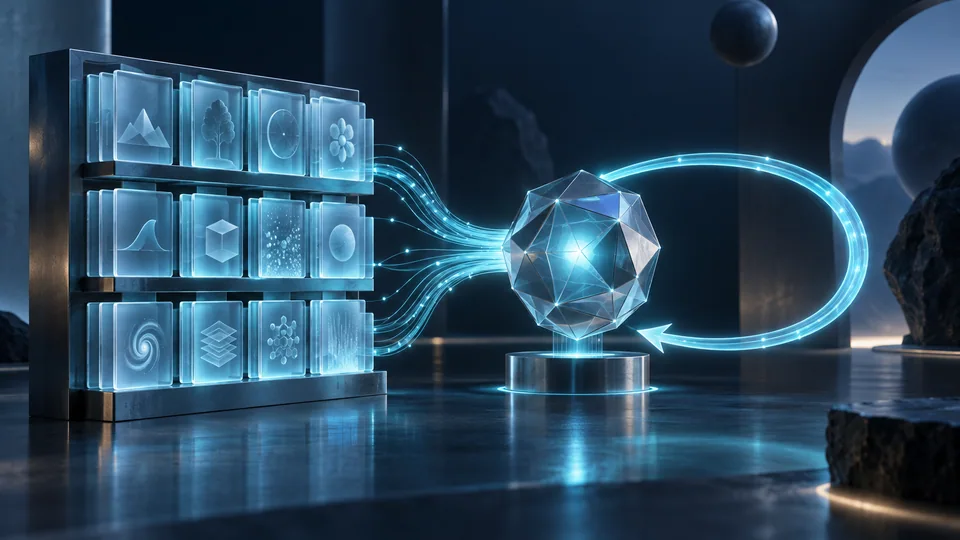
On September 22, OpenAI announced improved prompt caching for GPT-6. It reuses computation for repeated instructions and reference material. Eligible shared prefixes reused within 30 minutes receive cache discounts.
New tools show cache hit rates and explain misses. Discounts reach up to 90% on eligible cached input, not the whole bill. Developers can also adjust reasoning effort between responses while preserving reusable context under the documented conditions.
Our analysis
Organized reference material becomes an operating advantage
Our view is that organizing information can become as consequential as choosing a model. Separating stable manuals from changing instructions reduces repeated processing, giving well-organized teams a cost advantage even with the same AI.
Those savings could fund alternative drafts and extra checks. The benefit need not stop at doing the same job cheaply: teams may afford verification they previously skipped.
How could everyday life change?
The following is a possible future based on this news.
A small shop could afford an AI that knows its routines
A future shop assistant might reuse product information and service policies for morning customer replies and afternoon promotions, with less waiting to process the same background again.
This is a possible use, not a promise of unlimited memory beyond the announced window. Better preparation could make sustained AI work practical for smaller businesses.